The Prospero Challenge is a small but surprisingly rich rendering benchmark from Matt Keeter. The input is a plain-text program containing thousands of mathematical expressions. Evaluate it over the square [-1, 1] x [-1, 1], color each pixel by the sign of the result, and it produces an image of text from The Tempest.
The challenge is to render that image as quickly as possible. A direct NumPy implementation is short and readable, but it spends a lot of time and memory on intermediate arrays. That makes Prospero a nice playground for compiler ideas, interval arithmetic, expression simplification, parallel evaluation, SIMD, GPU execution, and the tradeoff between startup cost and steady-state frame time.
The renderer above draws the 1024x1024 image entirely on the CPU, compiled to WebAssembly. Here's how it works.
First try: tiles and intervals
My first version used the standard trick for this kind of problem. Split the image into four tiles and evaluate the expression on each tile with interval arithmetic. If the whole interval is negative, the tile is inside the shape and can be filled. If it's positive, the tile is empty. Only tiles that straddle zero get split further, down to 16x16 pixels, which are evaluated pixel by pixel.
The intervals also let you simplify the program as you go down. If one side of a min is always smaller on a tile, the other side can't matter there, so it gets dropped from that tile's program. With OpenMP and batched evaluation of the small tiles, this got to about 2 ms per frame on my MacBook Air.
It's just a lot of small shapes
If you stare at the program long enough, you notice that it is one giant min of a few hundred small shapes, each describing a piece of a letter. For prospero.vm there are 7,866 instructions and 666 of these shapes, each only about 20 instructions long. Each shape covers a tiny part of the image, but the tiling approach still has to carry all of them around until the intervals rule them out.
So the faster version renders every shape on its own:
- Split. Walk down from the root through the nested
minnodes and collect every operand that isn't itself amin. These are the 666 terms the benchmark reports. - Simplify. Copy each term into a small program of its own, fold its constants, and note which parts are linear in x and y. Tests like
sqrt(e) - rbecomee - r², which has the same sign and is cheaper. - Bound. The shape is where the term is at most zero. Pushing that condition backwards through the term with interval arithmetic gives a range for each linear part, which is a pair of half-planes. Clipping the square against them gives a tight polygon around the shape, and its bounding box in pixels. 87 of the 666 shapes turn out to be empty and are skipped right here.
- Draw. Many shapes are axis-aligned bars, which fill their box exactly, so the box is just filled. Everything else gets the tiling treatment from before, but only inside its own small box.
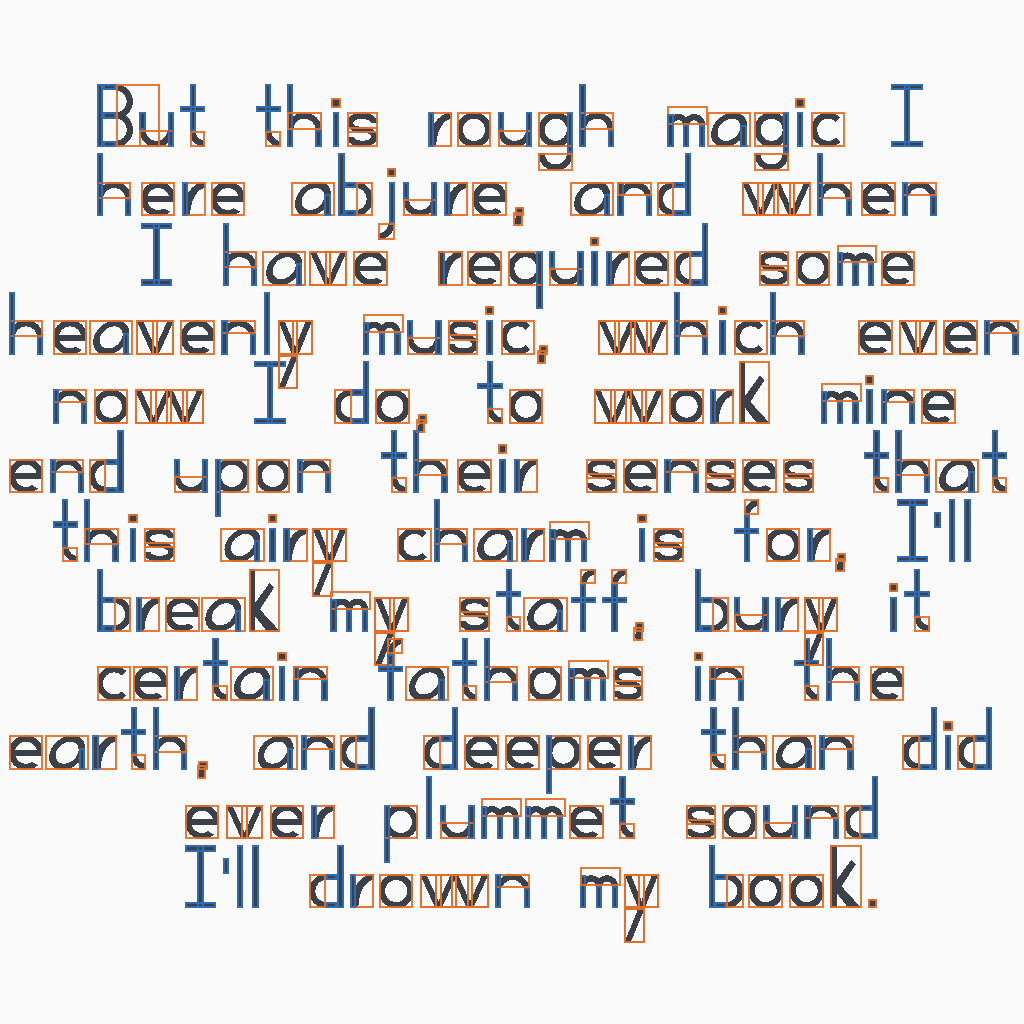
I tried this idea early on and gave up because pulling 700 programs out of the big one took over a millisecond. What makes it work is never copying the whole program: each frame only walks the min tree and each term's own nodes, and uses generation counters instead of clearing large arrays.
How much faster?
Single-threaded, on the same machine, the per-shape renderer is almost twice as fast as the improved tiling version and more than three times as fast as my first one:
| Version | ms per frame |
|---|---|
| Tiling, first version | ~21 |
| Tiling with better pruning and SIMD | ~11 |
| One shape at a time | ~6 |
Those numbers come from a slow 2-core cloud machine, so the ratios matter more than the absolute times. For a real number on your own device, run the benchmark at the top of the page.
The code is on GitHub.